镜像自地址
https://github.com/MINT-SJTU/Evo-RL.git
已同步 2026-11-20 18:17:06 +00:00
snapshot: sync mint main from current workspace 2026-03-03 16:32:56 +0800
这个提交包含在:
 Elvin
482
README.md
普通文件
482
README.md
普通文件
@ -0,0 +1,482 @@
|
||||
<h1 align="center">Evo-RL</h1>
|
||||
|
||||
<p align="center">
|
||||
<a href="https://elvin-yk.github.io/Evo-RL/"><img alt="project website" src="https://img.shields.io/badge/Project-Website-0ea5e9"/></a>
|
||||
<a href="https://github.com/huggingface/lerobot"><img alt="lerobot version" src="https://img.shields.io/badge/LeRobot-0.4.4-f59e0b"/></a>
|
||||
<a href="https://evorl.example.com/wechat-post"><img alt="wechat post" src="https://img.shields.io/badge/WeChat-Official%20Post-07c160"/></a>
|
||||
<a href="#community-channels"><img alt="wechat group join us" src="https://img.shields.io/badge/WeChat%20Group-Join%20Us-a855f7?logo=wechat&logoColor=white"/></a>
|
||||
<a href="#citation"><img alt="paper coming soon" src="https://img.shields.io/static/v1?label=Paper&message=Coming%20Soon&color=9ca3af"/></a>
|
||||
<a href="#model--dataset"><img alt="hugging face model coming soon" src="https://img.shields.io/static/v1?label=%F0%9F%A4%97%20Model&message=Coming%20Soon&color=9ca3af"/></a>
|
||||
<a href="#model--dataset"><img alt="hugging face dataset coming soon" src="https://img.shields.io/static/v1?label=%F0%9F%A4%97%20Dataset&message=Coming%20Soon&color=9ca3af"/></a>
|
||||
<a href="./LICENSE"><img alt="license" src="https://img.shields.io/badge/License-Apache--2.0-ef4444"/></a>
|
||||
</p>
|
||||
|
||||
<p align="center"><strong>SJTU & Evo-Tech</strong></p>
|
||||
|
||||
<p align="center"><strong>Architecture Overview</strong></p>
|
||||
|
||||
<p align="center">
|
||||
<img alt="Evo-RL Pipeline Overview" src="./website/assets/images/overview.png" width="96%"/>
|
||||
</p>
|
||||
|
||||
## 🎯 Evo-RL Focus
|
||||
|
||||
- **Open real-world RL on two platforms**: we build and release full real-world RL pipelines on SO101 and AgileX PiPER.
|
||||
- **Open code, models, and datasets for reproducibility**: we continuously release runnable offline RL assets so more people can reproduce results and apply them to real-world tasks.
|
||||
- **Open algorithm and community co-evolution**: we reproduce existing real-world RL methods, propose new methods, and keep publishing data/benchmarks to grow a collaborative open-source community.
|
||||
|
||||
## 🚀 News
|
||||
|
||||
- **[2026-02-26]** First SO101 real-world RL baseline and reproducible CLI workflow are released.
|
||||
|
||||
<p align="center"><strong>Value Visual Results</strong></p>
|
||||
|
||||
<p align="center"><small><strong>Success Case</strong></small></p>
|
||||
|
||||
<p align="center">
|
||||
<img alt="Value Overlay Success Episode 0405" src="./website/assets/gifs/value_success.gif" width="96%"/>
|
||||
</p>
|
||||
|
||||
<p align="center"><small><strong>Failure Case</strong></small></p>
|
||||
|
||||
<p align="center">
|
||||
<img alt="Value Overlay Failure Episode 0697" src="./website/assets/gifs/value_failure.gif" width="96%"/>
|
||||
</p>
|
||||
|
||||
<p align="center"><strong>Policy Rollout Visual Results</strong></p>
|
||||
|
||||
<p align="center">
|
||||
<img alt="Policy Rollout Result 1" src="./website/assets/gifs/policy_rollout_1.gif" width="48%"/>
|
||||
<img alt="Policy Rollout Result 2" src="./website/assets/gifs/policy_rollout_2.gif" width="48%"/>
|
||||
</p>
|
||||
|
||||
<p align="center"><strong>Human-in-the-Loop Visual Results</strong></p>
|
||||
|
||||
<p align="center">
|
||||
<img alt="Human-in-the-Loop Result 1" src="./website/assets/gifs/hitl_1.gif" width="48%"/>
|
||||
<img alt="Human-in-the-Loop Result 2" src="./website/assets/gifs/hitl_2.gif" width="48%"/>
|
||||
</p>
|
||||
|
||||
## ⚡ Quick Start
|
||||
|
||||
**LeRobot-aligned foundation:** we use LeRobot as the base of this codebase because its inference and data-collection logic are highly aligned with real-world RL workflows.
|
||||
|
||||
### 1) Installation
|
||||
|
||||
```bash
|
||||
git clone https://github.com/MINT-SJTU/Evo-RL.git
|
||||
cd Evo-RL
|
||||
conda create -y -n evo-rl python=3.10
|
||||
conda activate evo-rl
|
||||
pip install -e .
|
||||
```
|
||||
|
||||
For setup details and platform-specific dependencies, follow the official [LeRobot configuration guide](https://huggingface.co/docs/lerobot/installation).
|
||||
|
||||
### 2) Hardware Setup
|
||||
|
||||
#### SO101
|
||||
|
||||
Due to hardware limitations, SO100 is **not supported** for real-world reinforcement learning.
|
||||
|
||||
For SO101 setup, please follow the [official SO101 tutorial](https://wiki.seeedstudio.com/cn/lerobot_so100m/) in detail and complete all installation and configuration steps there before continuing.
|
||||
|
||||
#### Device path recommendation
|
||||
|
||||
Recommended path strategy:
|
||||
- **Robot serial:** use `/dev/serial/by-id/` (stable across reboots).
|
||||
- **Cameras:** prefer `/dev/v4l/by-id/`; if IDs are not unique, use `/dev/v4l/by-path/`.
|
||||
- In examples below: robot ports use `by-id`, camera paths use `by-path`.
|
||||
|
||||
You can inspect available stable paths with:
|
||||
|
||||
```bash
|
||||
ls -l /dev/serial/by-id/
|
||||
ls -l /dev/v4l/by-id/
|
||||
ls -l /dev/v4l/by-path/
|
||||
```
|
||||
|
||||
For single-arm users, no major changes are required. After setup, run the command below to verify your system is ready for the next stage:
|
||||
|
||||
```bash
|
||||
lerobot-teleoperate \
|
||||
--robot.type=so101_follower \
|
||||
--robot.port=/dev/serial/by-id/<SO101_FOLLOWER_PORT> \
|
||||
--robot.id=my_so101_follower \
|
||||
--teleop.type=so101_leader \
|
||||
--teleop.port=/dev/serial/by-id/<SO101_LEADER_PORT> \
|
||||
--teleop.id=my_so101_leader
|
||||
```
|
||||
|
||||
For dual-arm users, we recommend mirroring the mechanical parts corresponding to servos 4/5/6 on the left leader and left follower arms, which usually provides a more natural bimanual operation feel.
|
||||
|
||||
Before running the dual-arm command, make sure calibration files exist under `~/.cache/huggingface/lerobot/calibration/` like:
|
||||
|
||||
```text
|
||||
calibration/
|
||||
├── robots
|
||||
│ └── so_follower
|
||||
│ ├── bi_so101_follower_left.json
|
||||
│ └── bi_so101_follower_right.json
|
||||
└── teleoperators
|
||||
└── so_leader
|
||||
├── bi_so101_leader_left.json
|
||||
└── bi_so101_leader_right.json
|
||||
```
|
||||
|
||||
This layout is slightly different from single-arm setup.
|
||||
|
||||
Then run this command to verify dual-arm setup:
|
||||
|
||||
```bash
|
||||
lerobot-teleoperate \
|
||||
--robot.type=bi_so_follower \
|
||||
--robot.left_arm_config.port=/dev/serial/by-id/<LEFT_FOLLOWER_PORT> \
|
||||
--robot.right_arm_config.port=/dev/serial/by-id/<RIGHT_FOLLOWER_PORT> \
|
||||
--robot.id=bi_so101_follower \
|
||||
--teleop.type=bi_so_leader \
|
||||
--teleop.left_arm_config.port=/dev/serial/by-id/<LEFT_LEADER_PORT> \
|
||||
--teleop.right_arm_config.port=/dev/serial/by-id/<RIGHT_LEADER_PORT> \
|
||||
--teleop.id=bi_so101_leader
|
||||
```
|
||||
|
||||
#### Camera configuration
|
||||
|
||||
Before data collection, validate camera mapping first.
|
||||
|
||||
Check whether each camera supports your target setting (for example, `640x480 @ 30`):
|
||||
|
||||
```bash
|
||||
v4l2-ctl -d /dev/v4l/by-path/<CAM_PATH> --list-formats-ext
|
||||
```
|
||||
|
||||
Single-arm camera check (example):
|
||||
|
||||
```bash
|
||||
lerobot-teleoperate \
|
||||
--robot.type=so101_follower \
|
||||
--robot.port=/dev/serial/by-id/<SO101_FOLLOWER_PORT> \
|
||||
--robot.id=my_so101_follower \
|
||||
--robot.cameras='{ front: {type: opencv, index_or_path: "/dev/v4l/by-path/<FRONT_CAM>", width: 640, height: 480, fps: 30}}' \
|
||||
--teleop.type=so101_leader \
|
||||
--teleop.port=/dev/serial/by-id/<SO101_LEADER_PORT> \
|
||||
--teleop.id=my_so101_leader \
|
||||
--display_data=true
|
||||
```
|
||||
|
||||
Dual-arm camera check (example):
|
||||
|
||||
```bash
|
||||
lerobot-teleoperate \
|
||||
--robot.type=bi_so_follower \
|
||||
--robot.left_arm_config.port=/dev/serial/by-id/<LEFT_FOLLOWER_PORT> \
|
||||
--robot.right_arm_config.port=/dev/serial/by-id/<RIGHT_FOLLOWER_PORT> \
|
||||
--robot.id=my_bi_so101_follower \
|
||||
--robot.left_arm_config.cameras='{ wrist: {type: opencv, index_or_path: "/dev/v4l/by-path/<LEFT_WRIST_CAM_PATH>", width: 640, height: 480, fps: 30}}' \
|
||||
--robot.right_arm_config.cameras='{ wrist: {type: opencv, index_or_path: "/dev/v4l/by-path/<RIGHT_WRIST_CAM_PATH>", width: 640, height: 480, fps: 30}, front: {type: opencv, index_or_path: "/dev/v4l/by-path/<FRONT_CAM_PATH>", width: 640, height: 480, fps: 30}}' \
|
||||
--teleop.type=bi_so_leader \
|
||||
--teleop.left_arm_config.port=/dev/serial/by-id/<LEFT_LEADER_PORT> \
|
||||
--teleop.right_arm_config.port=/dev/serial/by-id/<RIGHT_LEADER_PORT> \
|
||||
--teleop.id=my_bi_so101_leader \
|
||||
--display_data=true
|
||||
```
|
||||
|
||||
For dual-arm camera mapping, it is fine to attach `front` under either the left-arm or right-arm camera config. If you use more camera views, place them under either the left or right arm camera config as well.
|
||||
|
||||
If needed, you can also use temporary device paths (for example `/dev/ttyACM*` and `/dev/video*`) during initial debugging.
|
||||
|
||||
### 3) Data Collection
|
||||
|
||||
Collect rollout data with `lerobot-human-inloop-record`. Bimanual template:
|
||||
|
||||
```bash
|
||||
lerobot-human-inloop-record \
|
||||
--robot.type=bi_so_follower \
|
||||
--robot.left_arm_config.port=/dev/serial/by-id/<LEFT_FOLLOWER_PORT> \
|
||||
--robot.right_arm_config.port=/dev/serial/by-id/<RIGHT_FOLLOWER_PORT> \
|
||||
--robot.id=my_bi_so101_follower \
|
||||
--robot.left_arm_config.cameras='{ wrist: {type: opencv, index_or_path: "/dev/v4l/by-path/<LEFT_WRIST_CAM_PATH>", width: 640, height: 480, fps: 30, fourcc: "MJPG"}}' \
|
||||
--robot.right_arm_config.cameras='{ wrist: {type: opencv, index_or_path: "/dev/v4l/by-path/<RIGHT_WRIST_CAM_PATH>", width: 640, height: 480, fps: 30, fourcc: "MJPG"}, front: {type: intelrealsense, serial_number_or_name: "<REALSENSE_SN>", width: 640, height: 480, fps: 30, warmup_s: 2}}' \
|
||||
--teleop.type=bi_so_leader \
|
||||
--teleop.left_arm_config.port=/dev/serial/by-id/<LEFT_LEADER_PORT> \
|
||||
--teleop.right_arm_config.port=/dev/serial/by-id/<RIGHT_LEADER_PORT> \
|
||||
--teleop.id=my_bi_so101_leader \
|
||||
--dataset.repo_id=<HF_USERNAME_OR_ORG>/<DATASET_NAME> \
|
||||
--dataset.single_task="<YOUR_TASK_DESCRIPTION>" \
|
||||
--dataset.num_episodes=<NUM_EPISODES> \
|
||||
--dataset.episode_time_s=<EPISODE_SECONDS> \
|
||||
--dataset.reset_time_s=<RESET_SECONDS> \
|
||||
--dataset.push_to_hub=true \
|
||||
--display_data=true
|
||||
```
|
||||
|
||||
Recommendation: use **`fourcc: "MJPG"`** for OpenCV and **`warmup_s`** for RealSense. In this example `front` uses RealSense, but you can switch it to OpenCV with the same structure.
|
||||
|
||||
Hotkeys:
|
||||
- `i`: toggle intervention mode (policy <-> teleop takeover)
|
||||
- `s`: mark success and end current episode
|
||||
- `f`: mark failure and end current episode
|
||||
- `Right Arrow`: end the current loop early
|
||||
- `Left Arrow`: end early and re-record the current episode
|
||||
- `Esc`: stop the recording session
|
||||
|
||||
Quick quality check:
|
||||
|
||||
```bash
|
||||
lerobot-dataset-report --dataset <HF_USERNAME_OR_ORG>/<DATASET_NAME>
|
||||
```
|
||||
|
||||
This prints: dataset meta, totals, episode-length stats/histogram, success/intervention metrics, task list, and full feature schema.
|
||||
|
||||
### 4) Value Function Training
|
||||
|
||||
Train the value function on the current dataset. Current default: [Pi*0.6](https://www.pi.website/blog/pistar06) (`--value.type=pistar06`).
|
||||
|
||||
Single-GPU template:
|
||||
|
||||
```bash
|
||||
lerobot-value-train \
|
||||
--dataset.repo_id=<HF_USERNAME_OR_ORG>/<DATASET_NAME> \
|
||||
--value.type=pistar06 \
|
||||
--value.dtype=bfloat16 \
|
||||
--value.push_to_hub=true \
|
||||
--value.repo_id=<HF_USERNAME_OR_ORG>/<VALUE_MODEL_REPO> \
|
||||
--batch_size=64 \
|
||||
--output_dir=outputs/value_train/<RUN_NAME> \
|
||||
--job_name=<RUN_NAME> \
|
||||
--wandb.enable=true
|
||||
```
|
||||
|
||||
Multi-GPU template:
|
||||
|
||||
```bash
|
||||
CUDA_VISIBLE_DEVICES=<GPU_ID_LIST> accelerate launch \
|
||||
--multi_gpu \
|
||||
--num_processes=<NUM_GPUS> \
|
||||
--mixed_precision=bf16 \
|
||||
$(which lerobot-value-train) \
|
||||
--batch_size=32/<NUM_GPUS> \
|
||||
<VALUE_TRAIN_ARGS>
|
||||
```
|
||||
|
||||
To plug in a different value function, minimal path in this repo:
|
||||
- Add `src/lerobot/values/<your_value>/configuration_<your_value>.py` with `@PreTrainedConfig.register_subclass("<your_value>")`.
|
||||
- Add `src/lerobot/values/<your_value>/modeling_<your_value>.py` with `<YourValue>Policy(PreTrainedPolicy)` (implement at least `forward`, `predict_value`, and `build_training_raw_batch_hook` for `lerobot-value-train`).
|
||||
- Add `src/lerobot/values/<your_value>/processor_<your_value>.py` with `make_<your_value>_pre_post_processors(...)`.
|
||||
- Remove/replace the current `pistar06`-only type checks in `src/lerobot/configs/value_train.py` and `src/lerobot/scripts/lerobot_value_infer.py`.
|
||||
|
||||
### 5) Value Inference
|
||||
|
||||
Infer value signals and write value/advantage/indicator back to the dataset:
|
||||
- `value`: estimated return-to-go of the current frame.
|
||||
- `advantage`: relative improvement signal (higher means better-than-baseline trajectory quality).
|
||||
- `indicator`: binarized training tag derived from advantage.
|
||||
|
||||
Single-GPU template:
|
||||
|
||||
```bash
|
||||
lerobot-value-infer \
|
||||
--dataset.repo_id=<HF_USERNAME_OR_ORG>/<DATASET_NAME> \
|
||||
--inference.checkpoint_path=outputs/value_train/<RUN_NAME> \
|
||||
--runtime.device=cuda \
|
||||
--runtime.batch_size=64 \
|
||||
--acp.enable=true \
|
||||
--acp.n_step=50 \
|
||||
--acp.positive_ratio=0.3 \
|
||||
--acp.value_field=complementary_info.value_<TAG> \
|
||||
--acp.advantage_field=complementary_info.advantage_<TAG> \
|
||||
--acp.indicator_field=complementary_info.acp_indicator_<TAG> \
|
||||
--output_dir=outputs/value_infer/<RUN_NAME> \
|
||||
--job_name=<RUN_NAME>.infer
|
||||
```
|
||||
|
||||
Multi-GPU template:
|
||||
|
||||
```bash
|
||||
CUDA_VISIBLE_DEVICES=<GPU_ID_LIST> accelerate launch \
|
||||
--multi_gpu \
|
||||
--num_processes=<NUM_GPUS> \
|
||||
--mixed_precision=bf16 \
|
||||
$(which lerobot-value-infer) \
|
||||
<VALUE_INFER_ARGS>
|
||||
```
|
||||
|
||||
Parameter notes:
|
||||
- `--acp.n_step`: n-step advantage horizon.
|
||||
- `--acp.positive_ratio`: positive label ratio after advantage binarization (e.g., `0.3` = top 30% per task).
|
||||
|
||||
Expected new columns:
|
||||
- `complementary_info.value_<TAG>`
|
||||
- `complementary_info.advantage_<TAG>`
|
||||
- `complementary_info.acp_indicator_<TAG>`
|
||||
|
||||
These columns are written back to the original dataset specified by `--dataset.repo_id`.
|
||||
|
||||
Visualization (optional):
|
||||
- Enable with `--viz.enable=true`.
|
||||
- Output videos are saved to `outputs/value_infer/<RUN_NAME>/value/viz/`.
|
||||
- Each video overlays a value curve and per-frame text (`advantage`, `acp_indicator`) on top of camera frames.
|
||||
- You can control scope with:
|
||||
- `--viz.episodes=all` or ranges like `0-9,12`
|
||||
- `--viz.video_key=<CAMERA_KEY>` (default picks `front` if available)
|
||||
- `--viz.overwrite=true|false`
|
||||
- `--viz.vcodec=<CODEC>` and `--viz.frame_storage_mode=memory|disk`
|
||||
|
||||
Value overlay examples (SO101, smooth=11):
|
||||
- GIF assets are stored under `website/assets/gifs/`.
|
||||
|
||||
### 6) Policy Training
|
||||
|
||||
Train the policy with advantage-conditioned tags.
|
||||
**Policy requirement:** it must support **text/task input**, because Advantage-Conditioned tags are injected into **task text**.
|
||||
|
||||
Single-GPU template:
|
||||
|
||||
```bash
|
||||
lerobot-train \
|
||||
--dataset.repo_id=<HF_USERNAME_OR_ORG>/<DATASET_NAME> \
|
||||
--policy.type=<POLICY_TYPE> \
|
||||
--policy.pretrained_path=<POLICY_PRETRAINED_PATH> \
|
||||
--policy.device=cuda \
|
||||
--policy.dtype=bfloat16 \
|
||||
--batch_size=32 \
|
||||
--steps=30000 \
|
||||
--acp.enable=true \
|
||||
--acp.indicator_field=complementary_info.acp_indicator_<TAG> \
|
||||
--acp.indicator_dropout_prob=0.3 \
|
||||
--output_dir=outputs/train/<RUN_NAME> \
|
||||
--job_name=<RUN_NAME> \
|
||||
--wandb.enable=true \
|
||||
--policy.push_to_hub=true \
|
||||
--policy.repo_id=<HF_USERNAME_OR_ORG>/<POLICY_REPO>
|
||||
```
|
||||
|
||||
`--acp.indicator_dropout_prob` controls tag drop rate in task text; `0.3` helps learn both tagged and untagged conditions.
|
||||
|
||||
Important checks:
|
||||
- `--acp.indicator_field` must exist in the dataset and be **binary (`0/1`)**.
|
||||
|
||||
Multi-GPU template:
|
||||
|
||||
```bash
|
||||
CUDA_VISIBLE_DEVICES=<GPU_ID_LIST> accelerate launch \
|
||||
--multi_gpu \
|
||||
--num_processes=<NUM_GPUS> \
|
||||
--mixed_precision=bf16 \
|
||||
$(which lerobot-train) \
|
||||
--batch_size=32/<NUM_GPUS> \
|
||||
<POLICY_TRAIN_ARGS>
|
||||
```
|
||||
|
||||
### 7) Closed-loop Rollout and Next Round
|
||||
|
||||
Deploy the trained policy in human-in-loop mode and collect the next dataset round:
|
||||
|
||||
```bash
|
||||
lerobot-human-inloop-record \
|
||||
--robot.type=bi_so_follower \
|
||||
--robot.left_arm_config.port=/dev/serial/by-id/<LEFT_FOLLOWER_PORT> \
|
||||
--robot.right_arm_config.port=/dev/serial/by-id/<RIGHT_FOLLOWER_PORT> \
|
||||
--robot.id=my_bi_so101_follower \
|
||||
--robot.left_arm_config.cameras='{ wrist: {type: opencv, index_or_path: "/dev/v4l/by-path/<LEFT_WRIST_CAM_PATH>", width: 640, height: 480, fps: 30, fourcc: "MJPG"}}' \
|
||||
--robot.right_arm_config.cameras='{ wrist: {type: opencv, index_or_path: "/dev/v4l/by-path/<RIGHT_WRIST_CAM_PATH>", width: 640, height: 480, fps: 30, fourcc: "MJPG"}, front: {type: intelrealsense, serial_number_or_name: "<REALSENSE_SN>", width: 640, height: 480, fps: 30, warmup_s: 2}}' \
|
||||
--teleop.type=bi_so_leader \
|
||||
--teleop.left_arm_config.port=/dev/serial/by-id/<LEFT_LEADER_PORT> \
|
||||
--teleop.right_arm_config.port=/dev/serial/by-id/<RIGHT_LEADER_PORT> \
|
||||
--teleop.id=my_bi_so101_leader \
|
||||
--dataset.repo_id=<HF_USERNAME_OR_ORG>/<DATASET_NAME_NEXT_ROUND> \
|
||||
--dataset.single_task="<YOUR_TASK_DESCRIPTION>" \
|
||||
--dataset.num_episodes=<NUM_EPISODES> \
|
||||
--dataset.episode_time_s=<EPISODE_SECONDS> \
|
||||
--dataset.reset_time_s=<RESET_SECONDS> \
|
||||
--dataset.push_to_hub=true \
|
||||
--display_data=true \
|
||||
--policy.path=<POLICY_CHECKPOINT_OR_HUB_ID> \
|
||||
--resume=true
|
||||
```
|
||||
|
||||
Dataset continuation options:
|
||||
- **Append in place:** keep `--resume=true` and continue recording into the same dataset.
|
||||
- **Merge multiple rounds:** use the official dataset editor to merge separate datasets.
|
||||
|
||||
```bash
|
||||
lerobot-edit-dataset \
|
||||
--repo_id=<HF_USERNAME_OR_ORG>/<MERGED_DATASET_NAME> \
|
||||
--operation.type=merge \
|
||||
--operation.repo_ids="['<HF_USERNAME_OR_ORG>/<DATASET_ROUND_1>','<HF_USERNAME_OR_ORG>/<DATASET_ROUND_2>']"
|
||||
```
|
||||
|
||||
Additional data attributes vs default `lerobot-record` behavior:
|
||||
- `complementary_info.policy_action`: policy output action at each step.
|
||||
- `complementary_info.is_intervention`: whether current step is in intervention.
|
||||
- `complementary_info.state`: intervention state-machine state.
|
||||
- `complementary_info.collector_policy_id`: step-level action source ID (`human` or policy ID).
|
||||
- Episode metadata `episode_success`: success/failure label saved per episode.
|
||||
|
||||
Iterative training loop (abstract):
|
||||
|
||||
```text
|
||||
[Multi-task demonstration data pool]
|
||||
|
|
||||
v
|
||||
[Offline RL pretraining for a vision-language-action policy]
|
||||
|
|
||||
v
|
||||
[Task-specific initialization / fine-tuning from demonstrations]
|
||||
|
|
||||
v
|
||||
|---- Iteration k = 1..K -------------------------------------|
|
||||
| 1) Deploy current policy π_k and collect new rollout data |
|
||||
| 2) Merge into data pool: D <- D U new_data |
|
||||
| 3) Train value function on D |
|
||||
| 4) Infer advantage and binarize into indicator tags |
|
||||
| 5) Train advantage-conditioned policy to get π_{k+1} |
|
||||
|-------------------------------------------------------------|
|
||||
|
|
||||
v
|
||||
[Stronger policy with improved success rate and throughput]
|
||||
```
|
||||
|
||||
## Model & Dataset
|
||||
|
||||
- Hugging Face model release: coming soon
|
||||
- Hugging Face dataset release: coming soon
|
||||
- Once published, this section will pin canonical repos and exact version tags.
|
||||
|
||||
## Community Channels
|
||||
|
||||
- WeChat official post: [Coming Soon](https://evorl.example.com/wechat-post)
|
||||
- Documentation: [`docs/README.md`](./docs/README.md)
|
||||
- GitHub Issues: [Create an issue](https://github.com/MINT-SJTU/Evo-RL/issues)
|
||||
- Email: business@evomind-tech.com
|
||||
- WeChat group QR code:
|
||||
|
||||
<p align="center">
|
||||
<img alt="EvoMind WeChat QR" src="./website/assets/images/evomind_wechat.jpg" width="220"/>
|
||||
</p>
|
||||
|
||||
## Affiliations
|
||||
|
||||
<p align="center">
|
||||
<img alt="SJTU community visual" src="./website/assets/images/sjtu.png" height="68"/>
|
||||
<img alt="EvoMind" src="./website/assets/images/evomind1.png" height="60"/>
|
||||
</p>
|
||||
|
||||
## Citation
|
||||
|
||||
```bibtex
|
||||
@misc{evorl2026,
|
||||
title = {Evo-RL: Continuous Open-Source Real-World RL on SO101 and Beyond},
|
||||
author = {Evo-RL Contributors},
|
||||
year = {2026},
|
||||
howpublished = {\url{https://github.com/MINT-SJTU/Evo-RL}}
|
||||
}
|
||||
```
|
||||
|
||||
## License
|
||||
|
||||
Apache-2.0. See [LICENSE](./LICENSE).
|
||||
|
||||
## Star History
|
||||
|
||||
[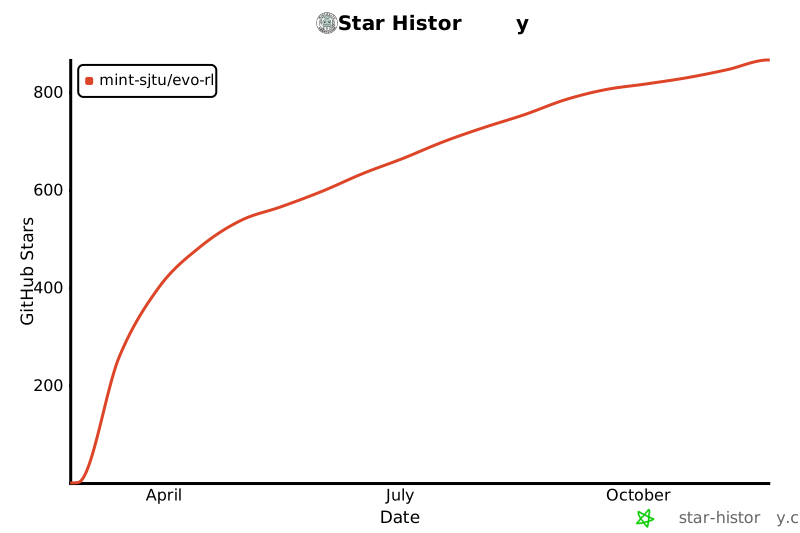](https://www.star-history.com/#MINT-SJTU/Evo-RL&Date)
|
||||
在新工单中引用
屏蔽一个用户